Adaptive Intelligence. Licensed Into Silicon.
Proprietary processor IP for adaptive, temporal, and event-driven AI processing licensed for ASIC and SoC integration.
WE BUILD THE IP. OUR CUSTOMERS BUILD THE SILICON.
Moving Computation to Memory, and Intelligence to the Edge.
Modern AI is constrained not by algorithms, but by silicon interconnects. JSA LAABS fuses SRAM storage directly with synaptic event-driven processors, delivering on-chip learning with zero off-chip memory thrashing.
The Memory Wall Has Broken Moore's Law.
In standard GPU/TPU architectures, 90% of energy is burned transporting weight tensors between HBM and compute units. NeuroCore fixes this at the physical silicon layer.
Off-Chip HBM Bottleneck
Backpropagation through time (BPTT) demands hundreds of gigabytes of activation cache, causing thermal throttling and high latency.
Fused In-Memory Compute
SRAM integrated processing eliminates external memory latency entirely, running localized learning updates in 142 microseconds.
Event-Driven Asynchronously Parallel MIMD
Autonomous multi-core MIMD execution that fires synaptic weights only when events occur, achieving 50× dynamic power reduction.
The Four Pillars of Cognitive Silicon
As you scroll, notice how each pillar directly targets one critical failure mode of legacy neural accelerators:
Unified Memory & MIMD Parallelism
Processing elements fused with SRAM storage execute event-driven threads asynchronously without clock synchronization penalties.
Bio-Realistic Local On-Chip Learning
Weights adapt locally in space and time in 142 microseconds, bypassing global gradient backpropagation memory overhead completely.
Second-Long Continuous Temporal Context
Maintains multi-second recurrent states natively in silicon memory for World Models, JEPA, and continuous sensor signal tracking.
Backward Compatible PyTorch / TensorFlow
Automated compiler toolchains seamlessly ingest standard PyTorch and TensorFlow networks into synthesized hardware-resident topologies.
Physical Single-Core Telemetry
Extracted directly from physical benchmark runs on a single NeuroCore tile. 142µs on-chip e-prop learning, 0.0ms zero-shot transfer, and zero catastrophic forgetting.
> [INIT] Synaptic plasticity core online. Weight buffer: Resident SRAM (0 HBM cycles)
> [TRAIN] E-prop temporal gradient calculated locally in space & time.
> [CONVERGED] On-chip weight update finalized in 142.4 µs. Peak temp: 34.2°C
> [EVAL] Zero-shot task inference latency: 0.00 ms. Memory delta: 0 bytes transferred off-chip.
Engineered for High-Consequence Frontiers
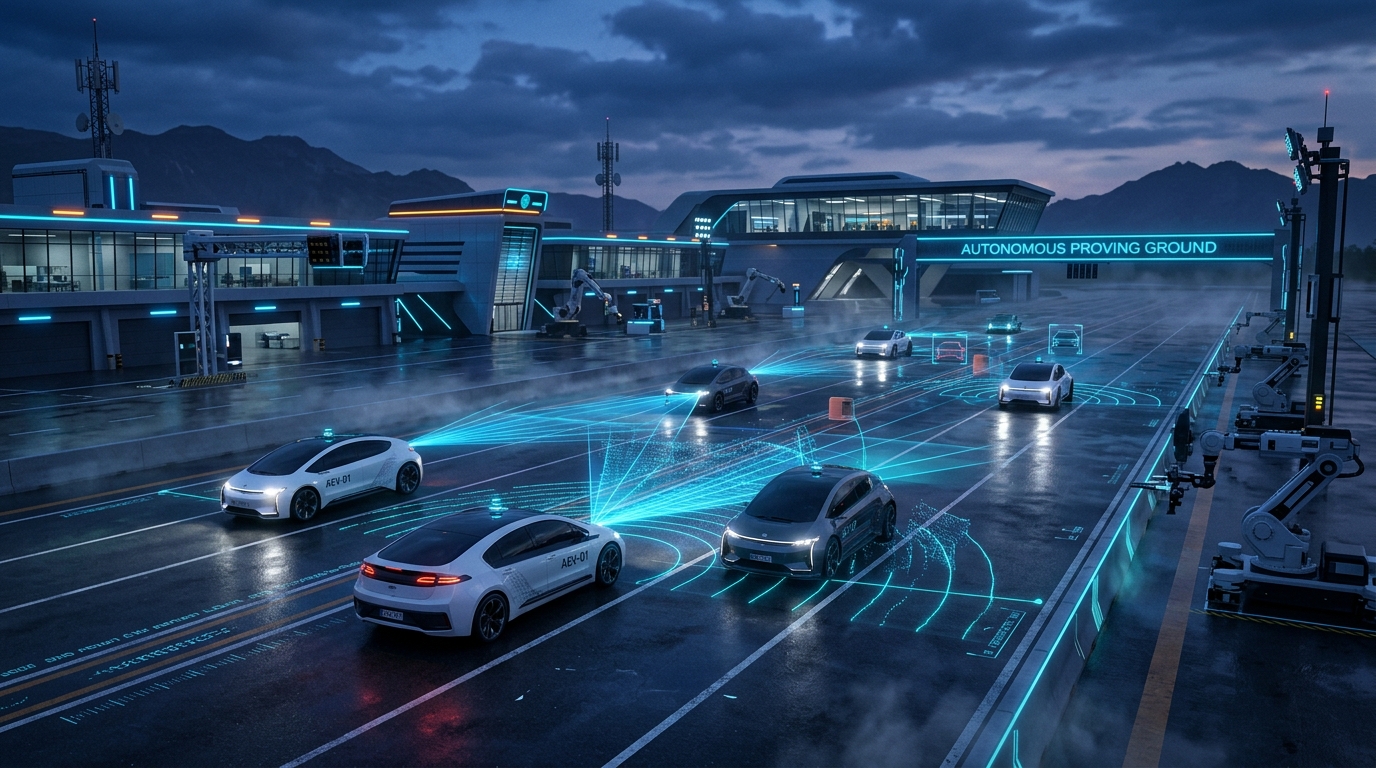
Where cloud connectivity is impossible, thermal ceilings are fixed, and real-time on-chip adaptation is non-negotiable.
Autonomous Vehicles
Real-time cabin monitoring (AIS-184 compliant) and perception sensor fusion adapting continuously to sensor drift and adverse weather.
Electronic Warfare
Microsecond cognitive radio frequency jamming mitigation and radar de-noising in high-threat environments without ground uplink.
Closed-Loop Actuation
Sub-millisecond reflex motor control with micro-joule energy budgets, completely eliminating the need for active cooling.
How Customers License & Integrate NeuroCore
As a fabless semiconductor IP foundry, JSA LAABS licenses complete digital and mixed-signal IP deliverables ready to be dropped into your target ASIC or SoC design flow.
IP Core Deliverable Suite
Synthesizable Verilog / SystemVerilog RTL, cycle-accurate C++ simulation models, timing constraints (SDC), and comprehensive verification testbenches.
Bus & Interconnect Fusion
Standard AXI4, TileLink, and OCP bus wrappers connect directly into host processors, DMA engines, and peripheral sensor interfaces with minimal routing congestion.
RTL to GDSII Verification
Proven physical design flows and timing closure verified across 7nm FinFET, 16nm, 28nm, and 45nm standard CMOS process design kits (PDKs).
License Adaptive AI Into Your Next Silicon Platform.
JSA LAABS licenses proprietary processor IP cores to fabless semiconductor design teams, Tier-1 automotive OEMs, and defense primes globally.
WE BUILD THE IP. OUR CUSTOMERS BUILD THE SILICON.